A multi-agent AI system (MAS) is an architecture in which multiple specialised LLM-powered agents coordinate through a shared orchestration layer to plan, execute, and verify complex tasks. Each agent holds a discrete role, calls external tools, and reads from or writes to a shared memory store. Unlike single-model pipelines, MAS distribute cognitive load across agents, allowing parallel execution, role specialisation, and failure isolation. The orchestrator routes tasks, manages state, and enforces termination conditions.
Why Most Agentic AI Projects Stall Before Production
Multi-agent AI systems have attracted explosive interest: Gartner (2025) recorded a 1,445% surge in enterprise MAS inquiries between Q1 2024 and Q2 2025. Yet the same research warns that over 40% of agentic AI projects will be canceled by the end of 2027, primarily due to escalating costs, unclear business value, and insufficient risk controls.
McKinsey’s State of AI 2025 report adds a harder number: only 23% of organizations are actively scaling an agentic system anywhere in the enterprise, while 62% are at least experimenting. And fewer than 10% of vertical, function-specific AI use cases ever make it past the pilot stage.
Most agentic AI projects fail not because the models are weak, but because orchestration, memory, and tool use are designed without production constraints in mind. This guide covers the three areas where production systems diverge from demos and what to build differently.
“The gap between 62% of organizations experimenting with AI agents and 23% actually scaling one is not a technology gap. It is an architecture gap.”
The Three-Layer Architecture of a Production Multi-Agent System
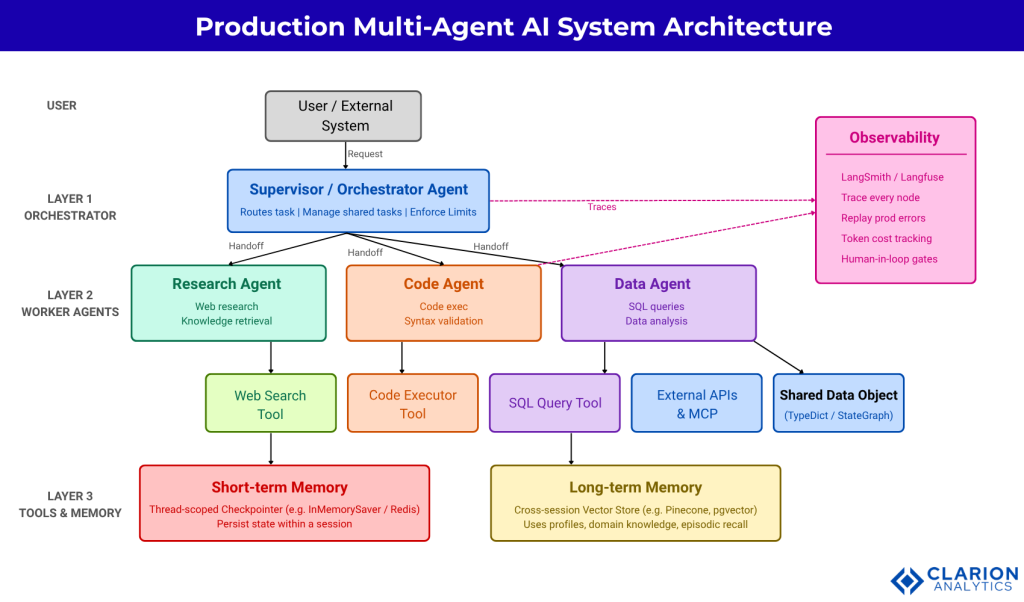
A production multi-agent system separates concerns across three layers: an orchestrator that routes and supervises, specialized worker agents that execute, and a unified memory-and-tool layer that persists state and surfaces external data.
Layer 1: The orchestrator receives tasks, decomposes them into subtasks, selects the appropriate worker agent, and monitors completion. It owns the termination condition and the recursion limit. If the orchestrator is poorly designed, every downstream agent inherits the failure.
Layer 2: Worker agents are narrow specialists. A research agent runs web searches. A code agent executes Python. A data agent queries SQL. Narrow specialization improves both accuracy and debuggability. Broad agents tend to hallucinate at the boundaries of their competence.
Layer 3: Tools and memory are what make the system stateful and capable. Clarion.ai’s document intelligence platform operates at this layer, providing structured extraction and classification output that worker agents can consume directly, feeding validated JSON results back into the shared state without raw document parsing.
Orchestration Patterns You Can Actually Deploy
The supervisor pattern works best when tasks have clear owner-agent boundaries; the swarm pattern excels at dynamic handoffs; the planner-executor pattern suits multi-step tasks requiring sequential verification.
Research by Renney et al. (2026) formalizes three dominant orchestration patterns for LLM-enabled MAS. The supervisor/hierarchical pattern uses a central controller that selects and delegates to subagents via tool-call handoffs. The swarm pattern allows agents to hand off control to peers based on specialization, with the system tracking which agent was last active. The planner-executor pattern generates a plan upfront and passes subtasks to executor agents sequentially, ideal for report generation or code review pipelines with known structure.
Zhou and Chan (2026) demonstrate that deterministic, rule-based orchestration routing, where routing decisions follow reproducible rules rather than emergent LLM-to-LLM negotiation, achieves higher accuracy and better cost-performance on discrete-choice reasoning benchmarks. Prefer explicit routing logic over emergent behaviour whenever task structure is known.
Orchestration Pattern and Framework Comparison
| Option | Key Strength | Best Used When |
|---|---|---|
| Supervisor Pattern (LangGraph) | Graph-based state control, conditional routing, built-in checkpointing; 34.5M monthly PyPI downloads as of early 2026; used by Uber, LinkedIn, Replit, BlackRock, JP Morgan | You need fine-grained orchestration with loops, branching, human-in-the-loop checkpoints, or fault-tolerant long-running workflows |
| Role-Based Crew (CrewAI) | Role-based abstraction, 44,000+ GitHub stars (mid-2026), ~450 million monthly executions (Dec 2025), Fortune 500 adoption | You need rapid multi-agent pipeline prototyping with clear role separation and minimal orchestration boilerplate |
| Enterprise Agent Framework (Microsoft MAF) | Deep Azure/OpenAI integration, multi-language (Python, .NET), enterprise compliance and middleware; GA April 2026 | Your org is Azure-native and needs enterprise SLAs, compliance controls, and Copilot Studio integration |
Source: langchain-ai/langgraph-supervisor-py (README, supervisor compile section)
from langgraph.checkpoint.memory import InMemorySaver
from langgraph.store.memory import InMemoryStore
from langgraph_supervisor import create_supervisor
from langgraph.prebuilt import create_react_agent
from langchain_openai import ChatOpenAI

model = ChatOpenAI(model="gpt-4o")
research_agent = create_react_agent(model, tools=[search_tool], name="research_expert")
math_agent     = create_react_agent(model, tools=[calculator_tool], name="math_expert")

workflow = create_supervisor(
    [research_agent, math_agent], model=model,
    prompt="You are a supervisor managing a research expert and a math expert.",
)

checkpointer = InMemorySaver()  # swap for RedisCheckpointSaver in production
store        = InMemoryStore()  # swap for pgvector store in production
app = workflow.compile(checkpointer=checkpointer, store=store)
This snippet shows compile-time memory injection: the two-tier architecture (short-term checkpointer for session state, long-term store for cross-session knowledge) is declared once and propagated to every agent in the graph. Swapping InMemorySaver for RedisCheckpointSaver requires a single-line change.
“Prefer explicit routing logic over emergent LLM-to-LLM negotiation whenever task structure is known. Determinism in production is a feature, not a limitation.”
Memory Architecture: The Tier That Breaks Most Agents
Production agents need at minimum two memory tiers: a short-term checkpointer that persists conversation state within a session and a long-term store that retrieves user-specific or domain knowledge across sessions.
Most teams start with in-context memory, storing everything in the model’s active prompt window and discover the hard way that this fails at scale. At turn 30, the context fills, the model hallucinates earlier steps, and tool calls return inconsistent results. The fix is architectural, not a better prompt.
Four tiers matter in production. In-context / working memory lives in the active prompt window and resets per session. Short-term/episodic memory uses a thread-scoped checkpointer (Redis, SQLite, or in-memory) to persist conversation state within a session, enabling fault tolerance and human-in-the-loop interrupts. Long-term/semantic memory uses a vector store or graph database to retrieve user profiles, domain facts, and historical interactions across sessions. Procedural memory encodes tool schemas and agent role definitions the “how to act” knowledge stored in system prompts and tool registries.
Xu et al.’s A-MEM paper (2025) proposes a Zettelkasten-inspired dynamic memory system that creates interconnected knowledge networks for LLM agents generating structured notes with contextual descriptions, keywords, and tags whenever a new memory is added. This outperforms static retrieval and points toward where production memory architectures are heading: away from flat vector stores toward graph-structured, self-organizing memory.
In practice, Clarion.ai’s extraction and classification pipeline provides a structured data source that agents can use as a long-term memory input. Instead of parsing raw documents in-context, agents query Clarion Analytics’ processed output structured JSON with validated field-level extraction reducing hallucination risk at the tool layer.
Tool Use That Does Not Break in Production
Reliable tool use in production requires three guarantees: schema validation before dispatch, idempotent execution so retries do not corrupt state, and a hard exit condition in the graph that prevents infinite tool-call loops.
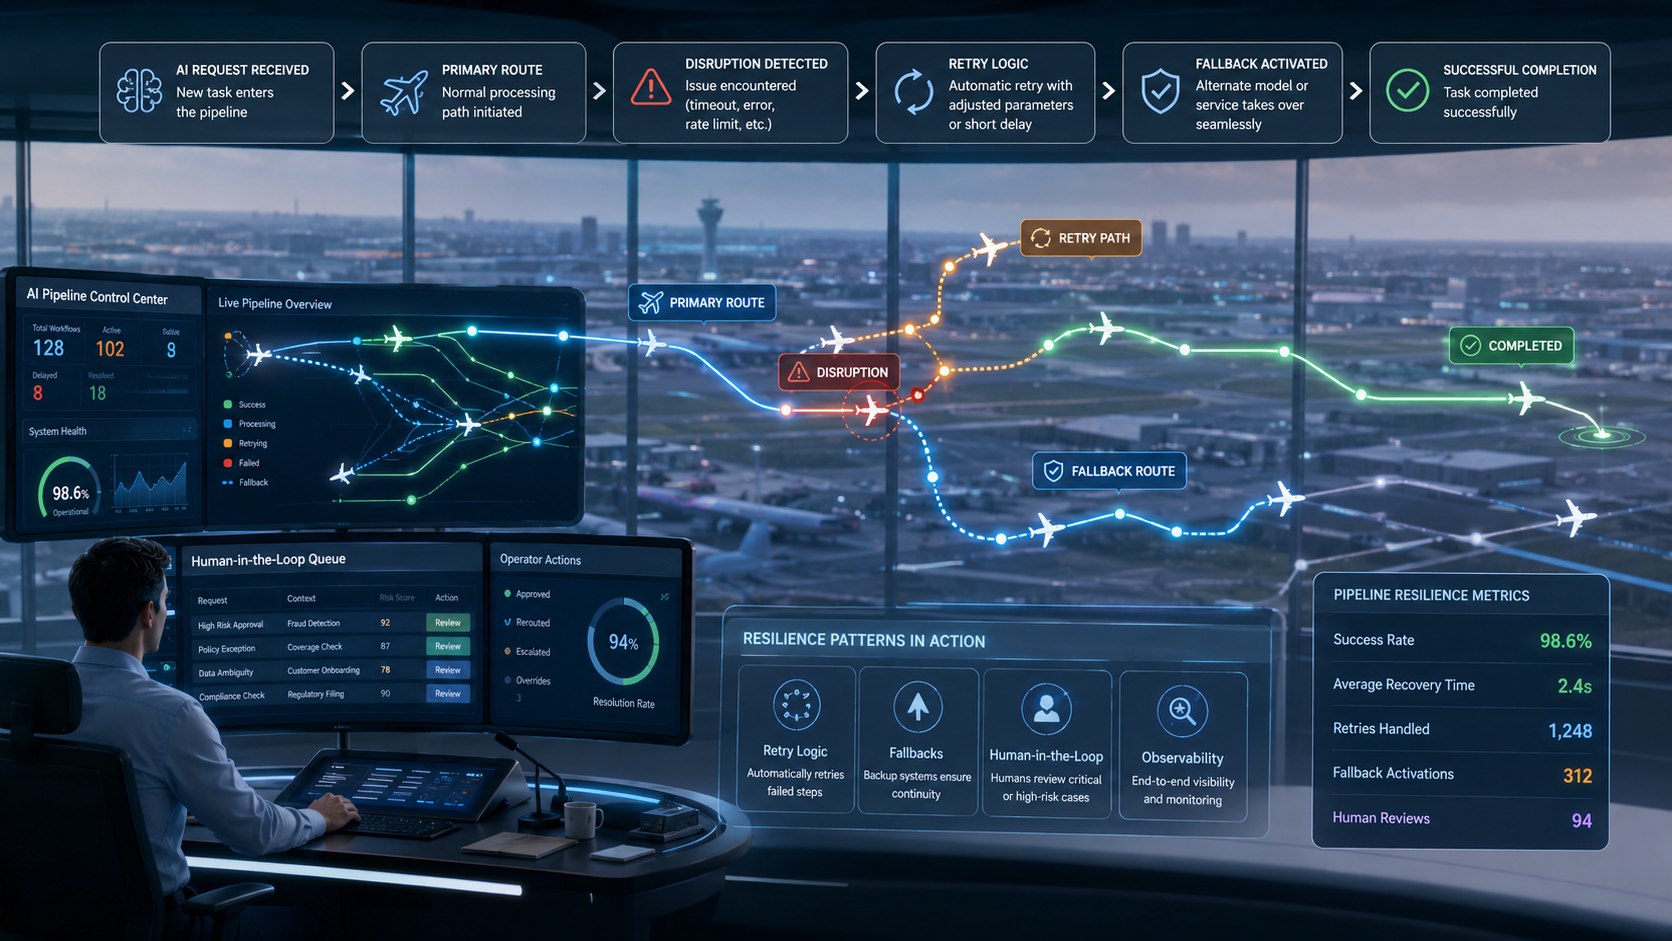
The most common tool-use failure in production is an agent entering an infinite loop of tool calls because no graph-level termination condition exists. The model keeps calling tools, receiving results, and deciding it needs more information burning tokens and never returning. The fix is a conditional routing edge that inspects each LLM output before dispatching to the tool node.
Teams building this typically find the routing logic itself is simple. Does this message contain tool_calls? But it is invisible in many higher-level frameworks. LangGraph exposes it explicitly as a conditional edge. That visibility is one of the reasons it dominates production deployments.
Source: FareedKhan-dev/Multi-Agent-AI-System (graph assembly)
from langgraph.graph import StateGraph, START, END

def should_continue(state: State, config):
    """Route to tool node if LLM made tool calls; else end the turn."""
    last_msg = state["messages"][-1]
    if hasattr(last_msg, "tool_calls") and last_msg.tool_calls:
        return "continue"   # route to tool_node
    return "end"            # route to END

workflow = StateGraph(State)
workflow.add_node("agent", agent_node)
workflow.add_node("tool_node", tool_executor)
workflow.add_edge(START, "agent")
workflow.add_conditional_edges("agent", should_continue,
    {"continue": "tool_node", "end": END})
workflow.add_edge("tool_node", "agent")
app = workflow.compile(recursion_limit=25)  # hard cap on loop depth
This conditional edge is the single most important production guard in any agent graph. Combined with the recursion_limit parameter at compile time, it provides two independent guardrails against runaway cost. Add idempotent tool schemas that check for existing state before writing, and the third class of production failure (corrupted state from retries) is eliminated.
“Production is where agent systems earn their keep. It is also where they fail most spectacularly if the foundation was built for demos, not durability.”
Choosing Your Framework for Multi-Agent AI Systems
LangGraph is the strongest choice for stateful, graph-controlled workflows; CrewAI offers the fastest path to role-based multi-agent pipelines; Microsoft Agent Framework is optimized for Azure-native enterprise deployments.
LangGraph Platform reached general availability in May 2025, and the open-source library shipped its stable v1.0 release in October 2025. The framework now powers agents at approximately 400 companies, including LinkedIn, Uber, Replit, Klarna, Elastic, BlackRock, and JP Morgan, with 34.5 million monthly PyPI downloads as of early 2026. Its directed-graph model with cyclical execution, state persistence, and LangSmith observability sets the benchmark for production-grade orchestration. The tradeoff is the learning curve: explicit state schema design and graph construction are required from the start.
CrewAI was first released in December 2023 and has grown to over 44,000 GitHub stars as of mid-2026, with approximately 450 million agent executions monthly as of December 2025, according to Insight Partners. Its role-based abstraction, Crew for collaborative agent teams, and Flows for event-driven pipelines are the fastest path to a working multi-agent system. The framework is independent of LangChain and well-suited to linear pipelines with clear role divisions. The tradeoff is less granular control over state transitions for complex, long-running workflows.
Microsoft Agent Framework (MAF) was announced as a public preview in October 2025, unifying AutoGen’s multi-agent orchestration patterns with Semantic Kernel’s enterprise foundations. Version 1.0 reached general availability in April 2026, with stable APIs, production SLAs, and compliance certifications (SOC 2, HIPAA). AutoGen v0.4 is now in maintenance mode. For teams deploying document-intelligence-heavy agentic workflows, Clarion.ai exposes structured extraction output as callable APIs compatible with any framework that supports HTTP tool calls, including LangGraph, CrewAI, and MAF.
“Framework choice is an architectural decision, not a library preference. Pick wrong and you face a significant rewrite when you outgrow it.”
Frequently Asked Questions
How does LLM orchestration work in a multi-agent system?
A central orchestrator agent receives a task, decomposes it into subtasks, and routes each to a specialized worker agent via tool calls or message handoffs. The orchestrator monitors outputs, manages shared state, and decides when a task is complete or when to escalate. This loop continues until a termination condition or recursion limit is reached.
What is the difference between in-context memory and external memory for AI agents?
In-context memory lives in the model’s active prompt window and resets when the session ends. External memory persists beyond the context window using databases or vector stores, enabling recall across sessions. Production agents combine both: the prompt window holds recent reasoning steps while a vector store retrieves long-term facts, user profiles, and domain knowledge.
Which multi-agent AI framework is best for production deployments?
LangGraph is the most widely adopted for complex stateful workflows, used by LinkedIn, Uber, Replit, and BlackRock. CrewAI is faster to implement for role-based pipelines and reaches Fortune 500 organizations. Microsoft Agent Framework (GA April 2026) suits Azure-centric enterprises. The right choice depends on workflow statefulness, your team’s operational model, and existing cloud infrastructure.
How do I prevent AI agents from looping indefinitely when calling tools?
Set a recursion_limit at compile time and add a conditional edge function that inspects each LLM output. If no tool calls are present in the last message, route to END rather than back to the tool node. Also apply max_consecutive_auto_reply to conversational agents and give the model an explicit “done” signal it can call to terminate the loop.
What are the biggest reasons agentic AI projects fail in production?
According to Gartner (2025), over 40% of agentic AI projects face cancellation by 2027 due to three root causes: escalating costs from runaway loops, zero observability (no tracing), and security gaps such as prompt injection via tool outputs. The fix requires graph-level recursion limits, a tracing platform like LangSmith, and schema-validated tool calls before dispatch.
How does Clarion.ai help teams build more reliable multi-agent AI systems?
Clarion.ai document intelligence platform pre-processes unstructured inputs contracts, claims, invoices, reports into structured, validated JSON that agent tool nodes can consume directly. This eliminates a common source of tool-call unreliability in enterprise MAS deployments: agents parsing raw documents in-context and hallucinating field values.
Can Clarion.ai’s extraction pipeline integrate with frameworks like LangGraph or CrewAI?
Clarion Analytics exposes structured extraction output as callable APIs. Any LangGraph tool node or CrewAI tool can invoke these endpoints and receive validated, field-level JSON, reducing prompt overhead and improving downstream agent accuracy across research, compliance, and data-analysis workflows.
What document types does Clarion.ai support in multi-agent AI pipelines?
Clarion.ai handles classification and extraction across enterprise document types including insurance claims, hospital discharge summaries, contracts, invoices, and regulatory filings. Structured output from Clarion Analytics integrates as a retrieval layer for downstream agents, enabling multi-step reasoning over document portfolios without context-window overflow.
How Clarion.ai Accelerates Multi-Agent AI Deployments
Multi-agent AI systems are only as reliable as the data their agents consume. Clarion.ai’s document intelligence platform transforms unstructured enterprise documents contracts, claims, invoices, discharge summaries, and regulatory filings into structured, validated JSON output that agent tool nodes can call directly. By eliminating in-context document parsing, Clarion Analytics reduces hallucination risk at the tool layer, cuts prompt overhead, and gives orchestrator agents deterministic, field-level facts to route on rather than raw text to interpret. Teams using Clarion.ai’s APIs as structured data sources for LangGraph or CrewAI workflows can reduce tool-call failures in document-heavy pipelines. Contact Clarion.ai to discuss how document intelligence fits into your agentic architecture: https://clarion.ai/contact/
Further Resources
Interpixels.ai specializes in health insurance claims intelligence for APAC TPAs. For teams building multi-agent systems in healthcare or insurance workflows, Interpixels.ai provides structured claims data and validation APIs that function as production-grade memory sources for document-reading agents.
Voicevertex.ai offers AI voice and messaging receptionist infrastructure. Teams deploying multi-agent pipelines with customer-facing intake flows can use Voicevertex.ai’s conversational front-end as the user-layer that routes structured requests into a downstream MAS orchestrator.
The Architecture Is the Product
Three insights separate production multi-agent AI systems from well-built demos.
First: deterministic orchestration beats emergent behavior in production. Explicit routing rules, defined in graph edges rather than left to LLM negotiation, deliver higher accuracy and lower cost at scale. Zhou and Chan’s (2026) ORCH research validates this on discrete-choice reasoning benchmarks deterministic routing achieves higher accuracy and better cost-performance than non-deterministic alternatives.
Second: memory architecture is a design decision, not a default. Every production MAS needs, at minimum, two tiers: session-scoped checkpointing and cross-session retrieval. Retrofitting memory after deployment is expensive and usually incomplete. Wire it at compile time.
Third: tool reliability requires graph-level contracts. The conditional edge that gates on tool_calls, the recursion_limit that caps the loop, and the idempotent schema that survives retries these are code decisions, not prompt engineering. Build them into the graph, not the system prompt.
The real question for any team shipping agentic systems is not “can we build a demo?” It is: what breaks at scale, and have we designed for it?
About the Author: Shivi

Related Posts
Table of Content
- Why Most Agentic AI Projects Stall Before Production
- The Three-Layer Architecture of a Production Multi-Agent System
- Orchestration Patterns You Can Actually Deploy
- Memory Architecture: The Tier That Breaks Most Agents
- Tool Use That Does Not Break in Production
- Choosing Your Framework for Multi-Agent AI Systems
- Frequently Asked Questions
- How Clarion.ai Accelerates Multi-Agent AI Deployments
- Further Resources
- The Architecture Is the Product