Object detection in safety-critical environments means identifying and localizing objects in real time under conditions where a missed detection or a false positive can cause physical harm or system failure. The pipeline must satisfy hard latency budgets, deliver statistically bounded error rates, and operate deterministically on edge hardware. The two architectures competing for this role are CNN-based detectors (the YOLO family) and end-to-end transformer-based detectors (RT-DETR and its variants).
Why Getting This Decision Right Matters
In systems where the wrong answer injures a worker or halts a production line, architecture selection is a safety decision, not just an engineering preference. Latency spikes, non-deterministic post-processing, and missed small objects are structural properties of an architecture, not symptoms of poor tuning.
The global computer vision market reached USD 19.78 billion in 2024 and is projected to hit USD 112.10 billion by 2035 at a 17.3% CAGR (MarketsandMarkets, 2025), with autonomous vehicles, medical imaging, and industrial safety as primary drivers. Object detection safety-critical pipelines sit at the centre of every one of those verticals. Choosing the wrong architecture costs more than benchmark points. It can cost lives, regulatory approval, or both.
Deloitte’s 2026 State of AI in the Enterprise (surveying 3,235 business and IT leaders across 24 countries) found that only 34% of enterprises are truly reimagining their business models with AI, and most are still moving from pilot to full operational scale. That gap exists precisely because teams underestimate the distance between a benchmark score and a deployed, auditable, bounded-latency safety system.
“Choosing between YOLO and a transformer detector is not a model question. It is a system reliability question with legal and physical consequences.”
How YOLO-Family Detectors Work and Where They Break
YOLO models run a single forward pass through a convolutional backbone and predict bounding boxes and class probabilities simultaneously. The main structural risk in safety scenarios is Non-Maximum Suppression (NMS), a post-processing step that adds variable latency and can suppress valid detections in dense scenes.
The YOLO family has evolved rapidly. YOLO11 introduced the C3k2 (Cross Stage Partial with kernel size 2) block and C2PSA (Convolutional block with Parallel Spatial Attention) module for improved feature extraction. YOLOv12 (NeurIPS 2025, arXiv:2502.12524) introduced efficient area attention (A2) modules and R-ELAN residual blocks, achieving 40.6% mAP at 1.64 ms on a T4 GPU. YOLO26, Ultralytics’ January 2026 release, eliminated NMS entirely with a native end-to-end dual-head architecture, delivering up to 43% faster CPU inference than YOLO11 on equivalent hardware.
For teams targeting power-constrained edge hardware such as NVIDIA Jetson Orin, Hailo, or Coral, YOLO11 and YOLO26 remain the dominant deployment choice. Clarion Analytics leverages its NVIDIA Inception Partnership to deploy GPU-accelerated YOLO-based pipelines in live operational environments across oil and gas and construction sites.
Source: ultralytics/ultralytics (60,000+ GitHub stars, actively maintained through 2026)
from ultralytics import YOLO

# Load a trained safety-domain model
model = YOLO("yolo11n.pt")

# Export to TensorRT FP16 -- deterministic latency for edge safety systems
model.export(format="engine", half=True, device=0)

# Load the TensorRT engine and run bounded-latency inference
trt_model = YOLO("yolo11n.engine")
results = trt_model("frame.jpg", verbose=False)
This two-step export serializes the model into a TensorRT engine optimized for your specific GPU. The half=True flag enables FP16 precision, halving memory bandwidth with negligible accuracy loss. The resulting .engine file delivers hardware-native, deterministic latency, which is the foundation any safety certification discussion requires.
How Transformer-Based Detectors Work and Why They Now Qualify
Transformer-based detectors replace NMS with bipartite matching in the decoder, producing exactly one prediction per detected object. This structural change makes end-to-end latency more predictable and eliminates the duplicate or suppressed detection failures that NMS introduces in crowded frames.
The RT-DETR paper (CVPR 2024, arXiv:2304.08069) from a Baidu research team (Zhao, Lv et al.) was the breakthrough. Its hybrid encoder decouples intra-scale and cross-scale feature interaction, cutting inference time dramatically versus prior DETR variants. RT-DETR-R50 achieves 53.1% mAP on COCO val2017 at 108 FPS on a T4 GPU. RT-DETRv3 (accepted WACV 2025, arXiv:2409.08475) extended the R101 backbone to 54.6% mAP, surpassing YOLOv10-X on COCO at the same latency.
The safety-specific advantage of NMS-free inference is not only speed. NMS can merge overlapping detections or suppress legitimate hits when confidence scores are similar. In pedestrian detection at 40 metres, that suppression is a safety failure. The RT-DETR decoder avoids this structurally.
“A 3% mAP gap on a leaderboard can represent the difference between detecting a worker in a hazard zone and missing them entirely.”
Source: ultralytics/ultralytics RT-DETR integration
from ultralytics import RTDETR

# NMS-free transformer detector -- predictable latency in dense scenes
model = RTDETR("rtdetr-r50.pt")

# Single-pass inference: no NMS post-processing step
results = model("safety_camera_feed.jpg")

# Confidence and class output directly from the decoder
for box in results[0].boxes:
    print(f"Class: {box.cls}, Confidence: {box.conf:.3f}, Box: {box.xyxy}")
This code runs detection without any iterative NMS loop. The decoder outputs a fixed set of object predictions filtered by a confidence threshold, giving safety engineers a single, auditable inference path with no variable post-processing stage.
Benchmark Reality Check: What the Numbers Actually Mean
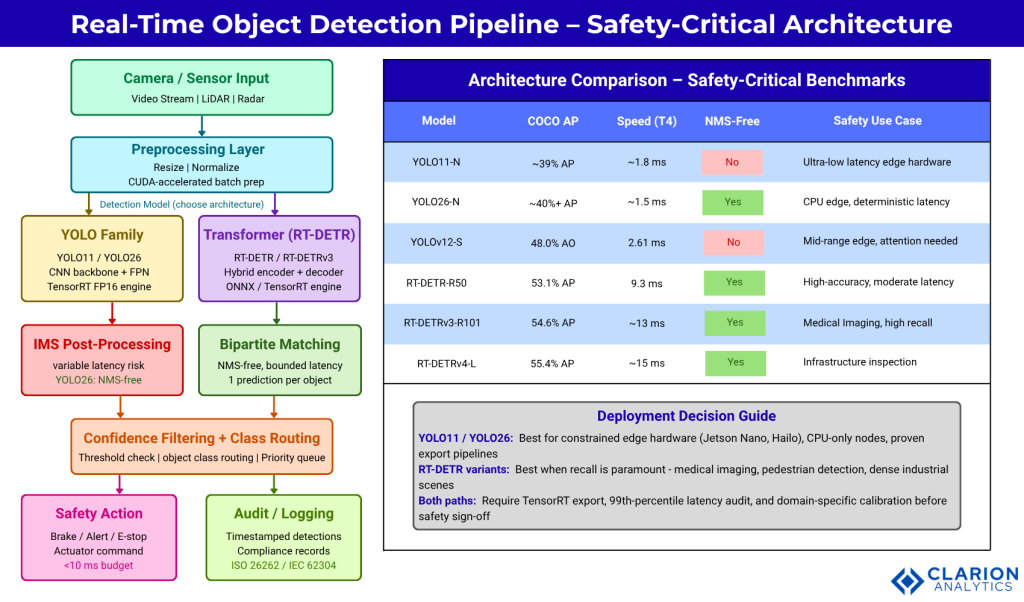
On a T4 GPU, YOLO11-N runs at approximately 1.8 ms while RT-DETR-R50 runs at approximately 9.3 ms. The comparison is not one-dimensional. Model scale, scene density, hardware target, and the acceptable precision-recall tradeoff all determine the right choice for a given safety specification.
| Option | Key Strength | Best Used When |
|---|---|---|
| YOLO11-N | Sub-2 ms, mature toolchain, multi-task support | Ultra-low latency on constrained edge hardware |
| YOLO26-N | NMS-free end-to-end, up to 43% faster CPU vs YOLO11 | CPU-only or power-limited nodes needing determinism |
| YOLOv12-S | Area attention + R-ELAN, 48.0% mAP at 2.6 ms | Mid-range edge where small-object recall matters |
| RT-DETR-R50 | 53.1% mAP, NMS-free, 108 FPS on T4 | Moderate GPU headroom, high-accuracy requirement |
| RT-DETRv3-R101 | 54.6% mAP, bipartite matching decoder | Medical imaging, dense pedestrian, high-recall mandates |
Always benchmark at the 99th-percentile latency on your target hardware. T4 results do not translate directly to Jetson Orin, Hailo, or CPU-only nodes.
Real-World Safety Use Cases: Choosing the Right Architecture
Autonomous vehicle perception pipelines, industrial PPE monitoring, and medical diagnostic imaging each have different dominant failure modes, and the architecture choice should follow from that.
In practice, teams building ADAS pipelines typically find that YOLO11 or YOLO26 on TensorRT FP16 meets the 30+ FPS floor required for sensor-fusion cycles, and domain fine-tuning on rain, night, and partial-occlusion datasets recovers the accuracy gap that appears on generic benchmarks. Clarion Analytics’ AegisVision AI deployed exactly this pattern for a multi-billion-dollar oil and gas company in India, achieving scalable PPE compliance monitoring across construction sites without proportionally expanding the safety workforce.
For medical imaging, the calculus reverses. False negatives carry catastrophic clinical cost. A missed pathology on a scan is not a recoverable error. The 1-2% mAP advantage of RT-DETRv3 over YOLO at comparable inference speeds justifies the additional compute when patient safety is the specification.
“The model that wins on COCO may not be the model that keeps the production line or the patient safe. Domain calibration and latency auditing are not optional steps.”
Implementation Path: From Trained Model to Certified Inference
Safety-critical deployment requires TensorRT FP16 export for deterministic latency, INT8 calibration for power-constrained nodes, a 99th-percentile latency audit on target hardware, and documented evaluation against domain-specific failure modes.
For INT8 calibration, collect at least 500 representative frames from your actual operating environment. ImageNet or COCO calibration data produces miscalibrated precision on domain-specific tasks. The Linaom1214/TensorRT-For-YOLO-Series repository provides tested TensorRT conversion scripts for YOLO11 and prior YOLO variants; verify YOLO26 support against the repository’s latest commit before deployment.
Frequently Asked Questions
Which is faster on edge hardware, YOLO or RT-DETR? YOLO models run faster at equivalent model size on constrained edge hardware. YOLO11-N runs under 2 ms on a T4 GPU; RT-DETR-R50 runs at approximately 9.3 ms. YOLO26’s NMS-free design closes the post-processing gap. On NVIDIA Jetson with TensorRT, both architectures can meet 30 FPS requirements at different accuracy operating points.
Does removing NMS with RT-DETR actually improve safety outcomes? Yes, in dense-object scenarios. NMS can suppress valid detections when two objects overlap with similar confidence scores. RT-DETR’s bipartite matching decoder guarantees one unique prediction per object. In pedestrian-dense or industrial scenes, this structural guarantee reduces false negatives at equivalent confidence thresholds, directly reducing missed safety events.
Can YOLO models match transformer accuracy for small-object detection? YOLOv12 and YOLO11 with spatial attention have closed much of the gap. YOLOv12-S beats RT-DETR-R18 on COCO while running 42% faster, using only 36% of the computation. For very small objects in safety contexts such as pedestrians beyond 50 metres or sub-32-pixel defects, RT-DETRv3’s hierarchical dense positive supervision consistently outperforms YOLO variants on domain-specific benchmarks.
What model format should I use for safety-critical edge deployment? TensorRT .engine files for NVIDIA hardware; ONNX for cross-platform portability. Never deploy raw PyTorch .pt files in production safety systems. TensorRT provides FP16 and INT8 precision options, deterministic graph execution, and measurable latency bounds. Calibrate on domain-specific frames, not public datasets.
How do I choose between YOLO11, YOLO26, and RT-DETR for my project? Use YOLO11 for multi-task stability on existing pipelines. Use YOLO26 for CPU-only or low-power edge nodes requiring NMS-free determinism. Choose RT-DETR variants when your safety specification mandates the highest achievable recall, especially in medical imaging or dense-crowd detection where missed objects carry the greatest operational and legal risk.
How does Clarion Analytics use object detection in safety systems? Clarion Analytics deploys its AegisVision AI product for worker safety monitoring in oil and gas, construction, and manufacturing. The platform detects PPE compliance events, hazard-zone breaches, and safety-procedure violations in real time across multiple camera feeds. Every deployment runs in live production operation, not a controlled demo environment.
Can Clarion Analytics help us select and deploy the right detector for our industry? Yes. Clarion Analytics provides end-to-end computer vision engineering, covering model selection, domain fine-tuning, TensorRT optimisation, and integration with site infrastructure. Every engagement is scoped to a defined operational outcome before development begins, covering oil and gas, healthcare, logistics, and construction environments.
Does Clarion Analytics support ongoing model monitoring after deployment? Yes. The Built. Deployed. Accountable. model means Clarion Analytics remains accountable after go-live, covering model drift monitoring, retraining triggers, and compliance audit log management. The team reviews performance in the live environment and responds to operational changes beyond project handover.
How Clarion Analytics Helps
Clarion Analytics builds production-grade computer vision systems for safety-critical environments across Asia Pacific. Its AegisVision AI product uses real-time object detection to monitor PPE compliance, detect hazard-zone breaches, and flag safety-procedure violations on construction sites and in oil and gas facilities. As an NVIDIA Inception Partner, Clarion Analytics has direct access to GPU acceleration technology that underpins TensorRT-optimized inference pipelines. The team handles the full implementation path: model selection, domain fine-tuning, TensorRT export, 99th-percentile latency validation, and audit log integration for ISO 26262 or IEC 62304 environments. Every engagement is committed to live production deployment, not a proof of concept.
Contact Clarion Analytics to discuss your safety detection requirements.
Further Resources
Interpixels.ai is a health insurance claims intelligence API built by Clarion Analytics. While its primary focus is document processing and claims adjudication for TPAs across Asia Pacific, it demonstrates the same production-grade AI deployment philosophy that underpins Clarion Analytics’ computer vision safety systems: trained on domain-specific data, integrated with live infrastructure, and accountable beyond go-live.
Voicevertex.ai is Clarion Analytics’ conversational voice AI platform, operating with sub-600ms latency across 70+ languages. For safety-critical environments that combine real-time visual monitoring with multilingual worker communication or incident reporting workflows, VoiceVertex AI provides the voice-layer complement to AegisVision AI’s visual detection capabilities.
Conclusion: Three Decisions That Define Your Detector Choice
Three insights should anchor your architecture selection. First, NMS is a correctness risk in dense scenes, not just a latency cost. YOLO26 and RT-DETR both offer NMS-free paths; safety systems should use one of them. Second, COCO mAP scores are starting points. A model with 2% lower mAP but 40% lower 99th-percentile latency on your actual hardware may be the safer operational choice. Third, the production deployment gap is real: only 34% of enterprises are truly reimagining their business models with AI (Deloitte, 2026), which means most teams are further from a fully deployable system than their benchmark results suggest. Export to TensorRT, calibrate on domain data, and audit latency under worst-case scene density before finalising any architecture.
Which failure mode matters most in your environment: latency spikes, missed small objects, or NMS suppression in dense scenes?
About the Author: Shivi

Related Posts